Benchmark · preview
Off-the-shelf detectors lose about 40% of their accuracy on Indian roads.
We ran 20 widely used object detectors, unchanged, on 904 dashcam frames from Delhi NCR that two of our annotators labelled independently. The best model scores 34.7. On COCO, the benchmark these models are built against, it scores 57.5.
- 59%
- of their COCO score is what these models keep on Indian roads. YOLO26x, the best here, scores 34.7 against 57.5 on COCO.
- 50%
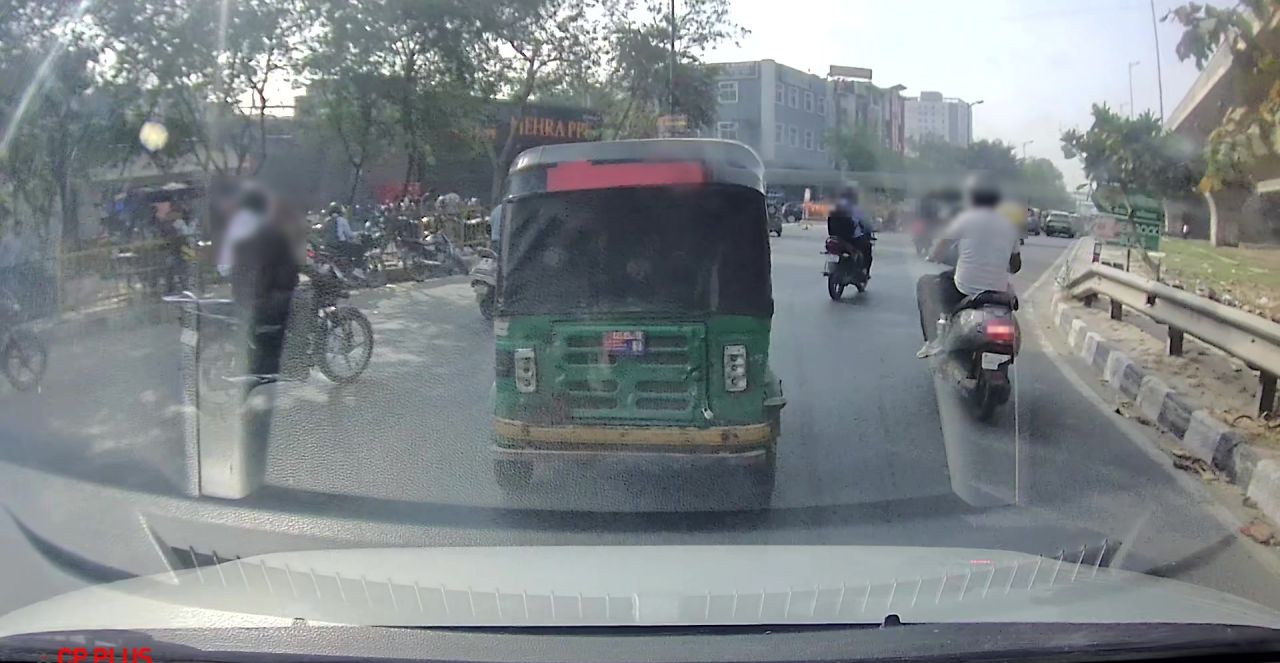
- of auto-rickshaws go unseen by YOLO26x. No COCO model has a class for them; the ones it does find, it calls trucks or cars.
- 7.1 pts
- lost at night, on average across all 20 models, and 4.8 in rain, against daytime frames.
- +2.1 pts
- is all that six years of YOLO releases add here, from YOLOv5x to YOLO26x. On COCO the same step is worth 4.3.
Leaderboard
Each model's score on our test set, out of 100: the standard COCO measure of how well its boxes match ours. Differences under one point are a tie.
| # | Model | Score on Indian roads | Keeps of its COCO score | At night | Auto-rickshaws found |
|---|---|---|---|---|---|
| 1 | YOLO26x | 34.7 | 60% | 30.9 | 50% |
| 2 | YOLOv8x | 33.8 | 63% | 30.0 | 54% |
| 3 | YOLO12x | 33.6 | 61% | 30.2 | 51% |
| 4 | YOLO11x | 33.5 | 61% | 29.8 | 53% |
| 5 | YOLO26m | 32.8 | 62% | 28.1 | 54% |
| 6 | YOLOv5x | 32.6 | 61% | 28.3 | 52% |
| 7 | YOLOv9e | 32.5 | 58% | 28.1 | 51% |
| 8 | YOLOv10m | 31.9 | 62% | 27.8 | 49% |
| 9 | YOLOv9c | 31.8 | 60% | 28.6 | 51% |
| 10 | RT-DETR-X | 31.6 | 58% | 29.8 | 75% |
| 11 | YOLO12m | 31.4 | 60% | 28.2 | 50% |
| 12 | YOLO11m | 31.3 | 61% | 27.8 | 53% |
| 13 | YOLOv10x | 31.2 | 57% | 29.2 | 49% |
| 14 | RT-DETR-L | 30.9 | 58% | 28.3 | 75% |
| 15 | YOLOv8m | 30.9 | 62% | 27.5 | 52% |
| 16 | Faster R-CNN v2 | 30.5 | 65% | 25.8 | 74% |
| 17 | RetinaNet v2 | 28.2 | 68% | 23.5 | 66% |
| 18 | YOLOv5s | 23.7 | 55% | 22.2 | 44% |
| 19 | YOLO11n | 18.6 | 47% | 17.3 | 40% |
| 20 | YOLOv8n | 18.2 | 49% | 17.4 | 38% |
All results, every column
- Score
- COCO-style mAP, IoU 0.50 to 0.95, on the eight classes a COCO model can name.
- COCO
- The model's published score on COCO, its home benchmark.
- Kept
- Our score as a share of its COCO score.
- AP50
- A looser score: a box counts if it overlaps ours by half.
- Near
- Only objects at least 32 pixels tall, the closer ones.
- Conditions
- Checked by hand on every frame; the number under each is how many test frames it covers.
| # | Model | Score | COCO | Kept | AP50 | Near | Day320 frames | Dusk or dawn119 frames | Night465 frames | Rain110 frames | Autos found |
|---|---|---|---|---|---|---|---|---|---|---|---|
| 1 | YOLO26x | 34.7 | 57.5 | 60% | 58.1 | 35.5 | 39.5 | 36.7 | 30.9 | 35.7 | 50% |
| 2 | YOLOv8x | 33.8 | 53.9 | 63% | 56.1 | 34.8 | 38.2 | 34.4 | 30.0 | 32.3 | 54% |
| 3 | YOLO12x | 33.6 | 55.2 | 61% | 55.4 | 34.6 | 37.3 | 35.9 | 30.2 | 34.6 | 51% |
| 4 | YOLO11x | 33.5 | 54.7 | 61% | 54.7 | 34.5 | 37.6 | 35.0 | 29.8 | 34.0 | 53% |
| 5 | YOLO26m | 32.8 | 53.1 | 62% | 53.5 | 33.7 | 37.5 | 35.6 | 28.1 | 28.9 | 54% |
| 6 | YOLOv5x | 32.6 | 53.2 | 61% | 54.1 | 33.6 | 37.5 | 34.2 | 28.3 | 32.4 | 52% |
| 7 | YOLOv9e | 32.5 | 55.6 | 58% | 55.3 | 33.2 | 37.9 | 35.9 | 28.1 | 32.4 | 51% |
| 8 | YOLOv10m | 31.9 | 51.1 | 62% | 52.5 | 32.8 | 36.9 | 33.6 | 27.8 | 31.8 | 49% |
| 9 | YOLOv9c | 31.8 | 53.0 | 60% | 51.8 | 32.8 | 35.0 | 34.1 | 28.6 | 28.6 | 51% |
| 10 | RT-DETR-X | 31.6 | 54.8 | 58% | 53.8 | 32.6 | 34.2 | 34.1 | 29.8 | 32.6 | 75% |
| 11 | YOLO12m | 31.4 | 52.5 | 60% | 51.5 | 32.3 | 34.7 | 35.2 | 28.2 | 32.8 | 50% |
| 12 | YOLO11m | 31.3 | 51.5 | 61% | 51.4 | 32.2 | 35.4 | 33.1 | 27.8 | 29.1 | 53% |
| 13 | YOLOv10x | 31.2 | 54.4 | 57% | 51.4 | 32.1 | 33.9 | 31.3 | 29.2 | 27.2 | 49% |
| 14 | RT-DETR-L | 30.9 | 53.0 | 58% | 53.6 | 31.7 | 34.2 | 32.8 | 28.3 | 30.0 | 75% |
| 15 | YOLOv8m | 30.9 | 50.2 | 62% | 51.5 | 31.8 | 35.0 | 31.8 | 27.5 | 30.1 | 52% |
| 16 | Faster R-CNN v2 | 30.5 | 46.7 | 65% | 55.8 | 31.6 | 35.8 | 33.3 | 25.8 | 28.2 | 74% |
| 17 | RetinaNet v2 | 28.2 | 41.5 | 68% | 50.4 | 29.1 | 34.4 | 28.2 | 23.5 | 26.5 | 66% |
| 18 | YOLOv5s | 23.7 | 43.0 | 55% | 39.2 | 24.4 | 25.7 | 23.9 | 22.2 | 21.5 | 44% |
| 19 | YOLO11n | 18.6 | 39.5 | 47% | 31.6 | 19.1 | 21.1 | 17.1 | 17.3 | 19.2 | 40% |
| 20 | YOLOv8n | 18.2 | 37.3 | 49% | 30.9 | 18.8 | 19.9 | 18.1 | 17.4 | 17.2 | 38% |
How far each model falls
The same models, on COCO and on Indian roads. The longer the line, the more accuracy a model loses when it leaves the benchmark it was built for.
- On COCO
- On Indian roads
- YOLO26x34.7 / 57.5
- YOLOv8x33.8 / 53.9
- YOLO12x33.6 / 55.2
- YOLO11x33.5 / 54.7
- YOLO26m32.8 / 53.1
- YOLOv5x32.6 / 53.2
- YOLOv9e32.5 / 55.6
- YOLOv10m31.9 / 51.1
- YOLOv9c31.8 / 53.0
- RT-DETR-X31.6 / 54.8
- YOLO12m31.4 / 52.5
- YOLO11m31.3 / 51.5
- YOLOv10x31.2 / 54.4
- RT-DETR-L30.9 / 53.0
- YOLOv8m30.9 / 50.2
- Faster R-CNN v230.5 / 46.7
- RetinaNet v228.2 / 41.5
- YOLOv5s23.7 / 43.0
- YOLO11n18.6 / 39.5
- YOLOv8n18.2 / 37.3
Accuracy by condition
Night is where every model struggles most. Rain sits between day and night: 84 of our 110 rain frames were filmed at night, so that bar mixes the two.
- Day320 frames34.1
- Dusk or dawn119 frames31.7
- Night465 frames26.9
- Rain110 frames29.3
What models call an auto-rickshaw
COCO has no auto-rickshaw class, so we count a hit when a model puts any vehicle box on one. Across all 2,511 auto-rickshaws in our frames, this is where they end up.
YOLO26x
YOLOv8x
RT-DETR-X
Faster R-CNN v2
- Missed
- Truck
- Car
- Bus
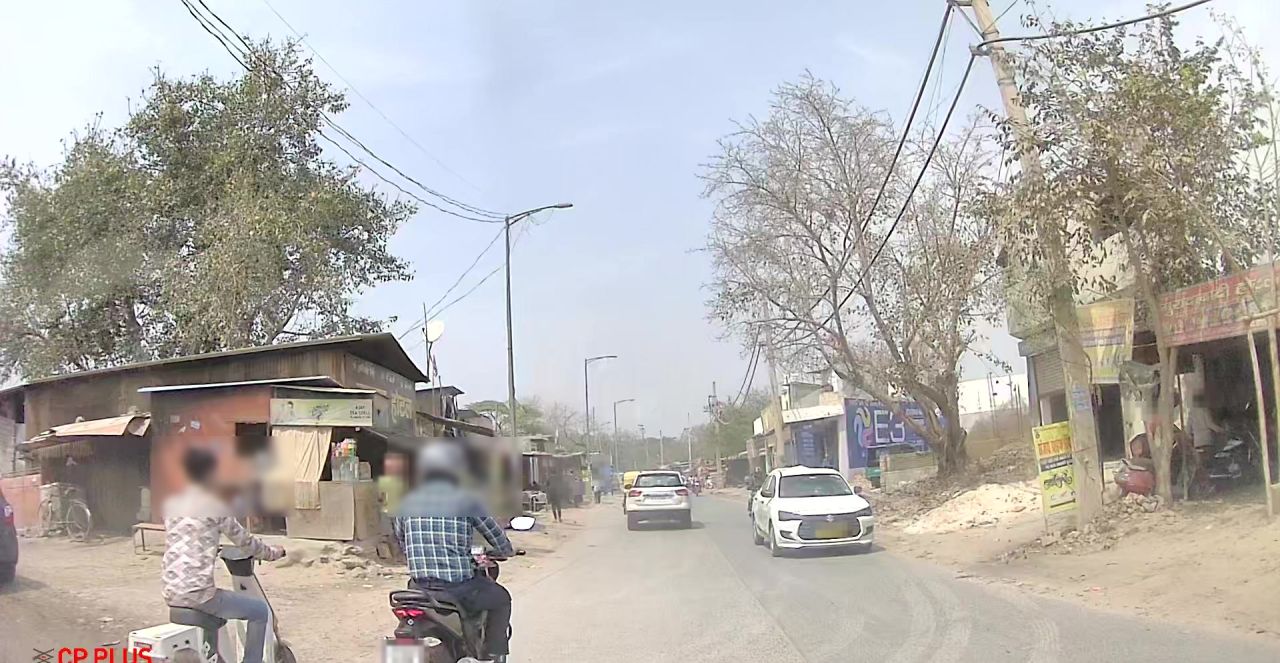
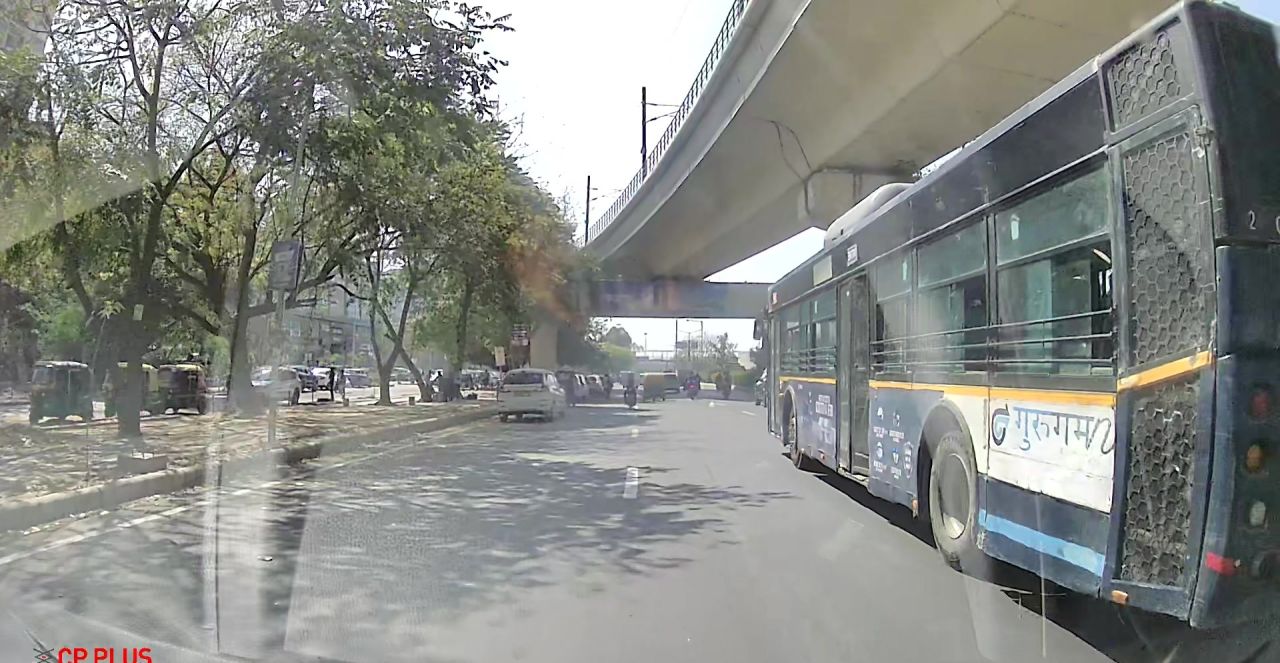
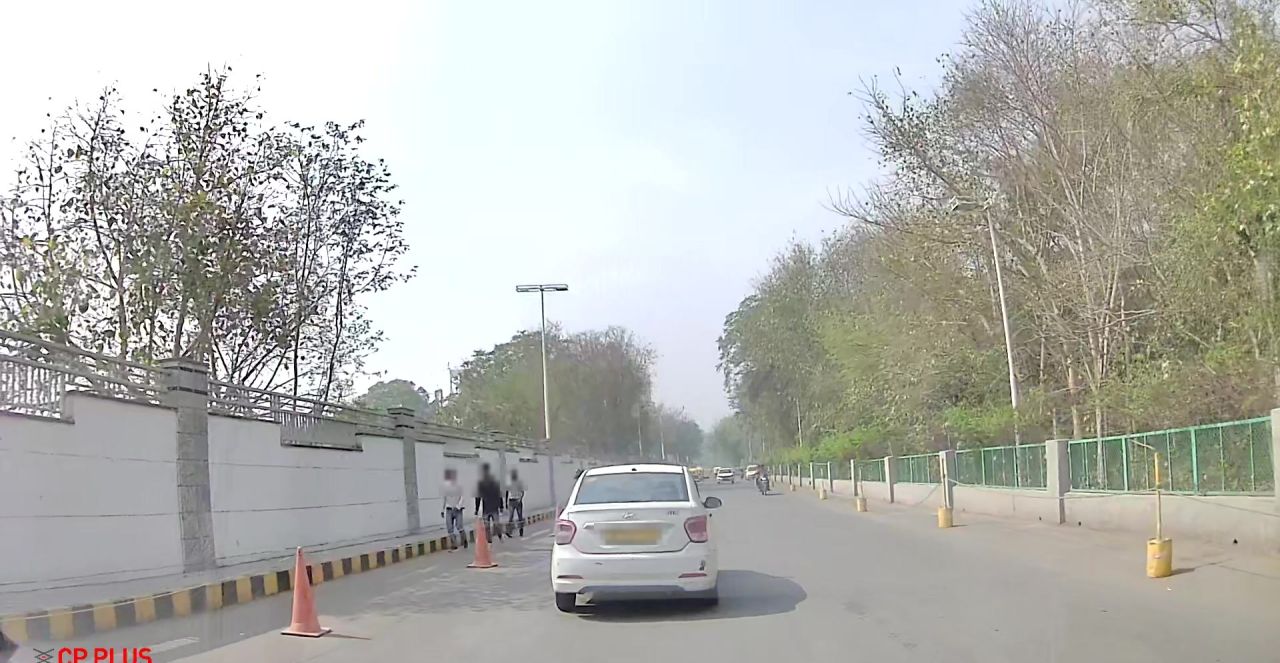
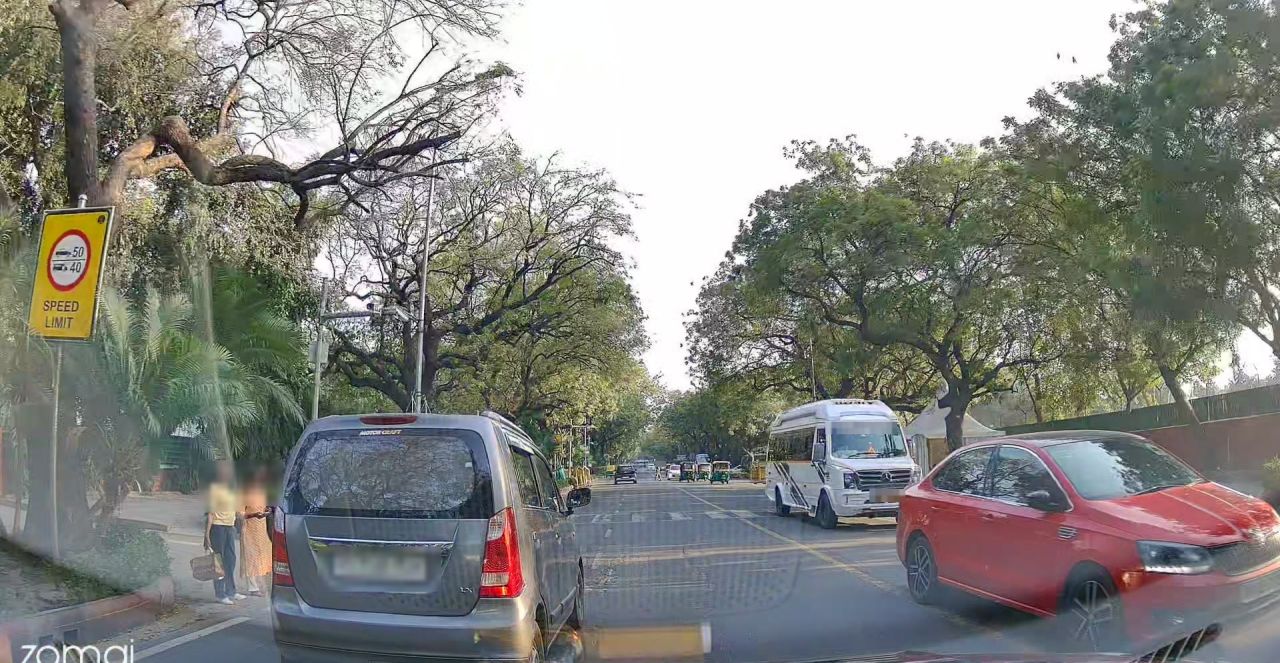
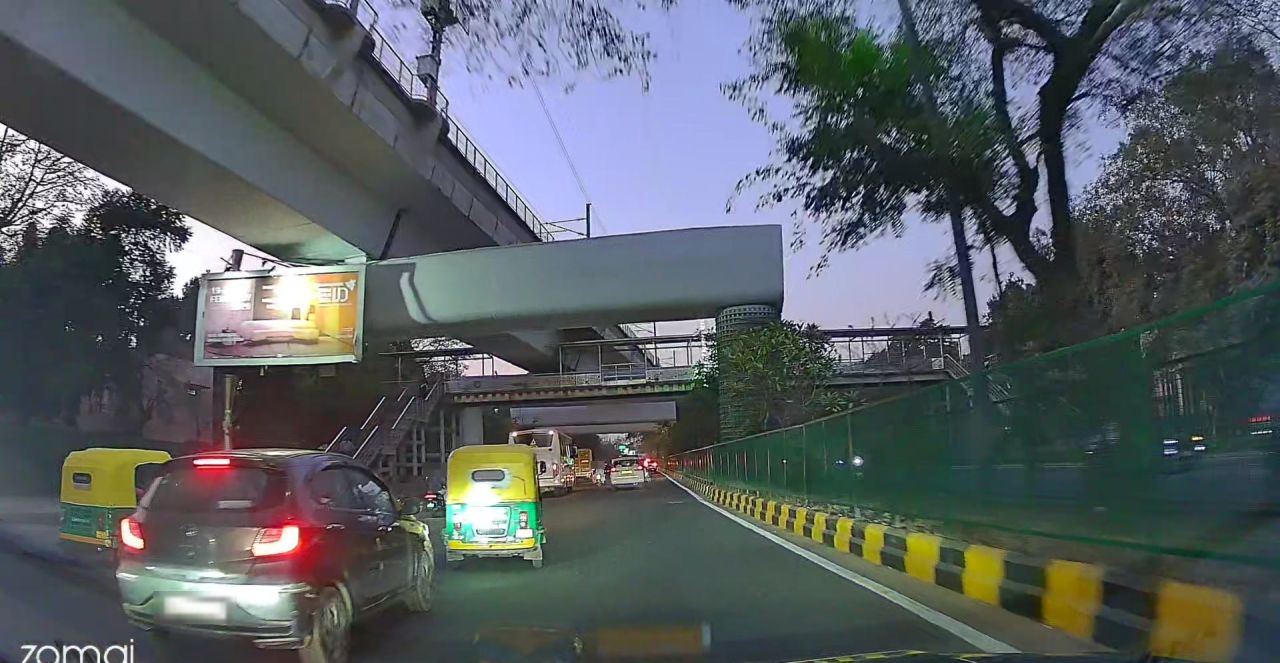
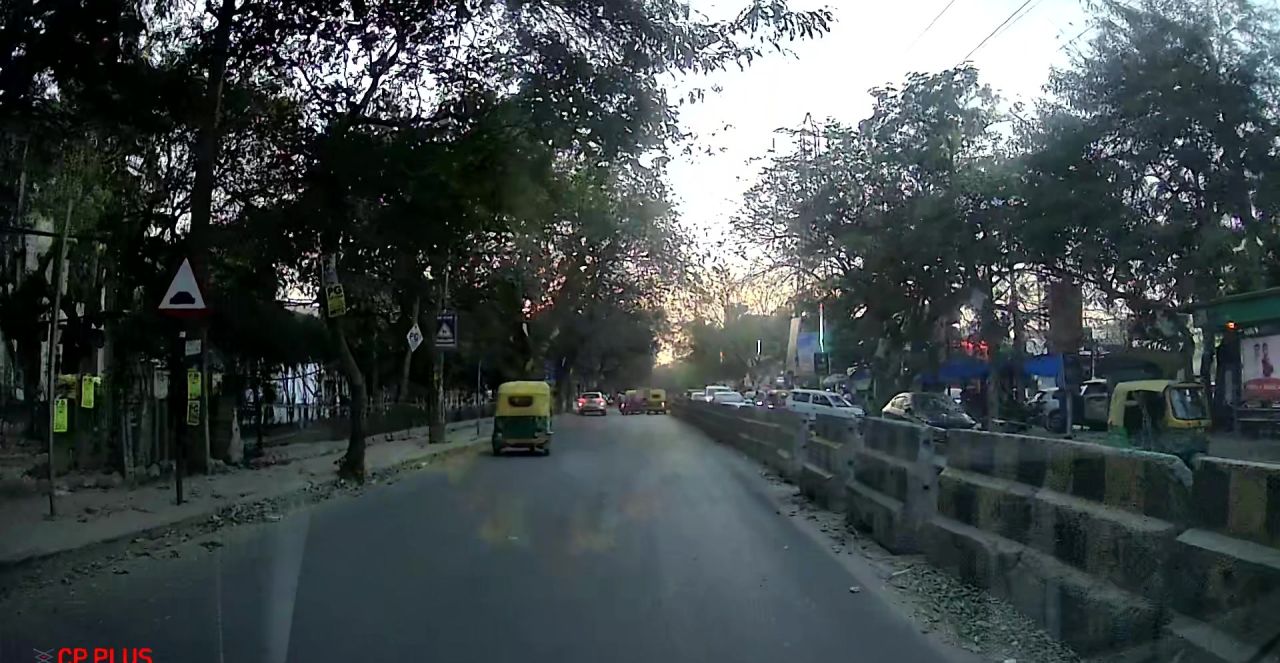
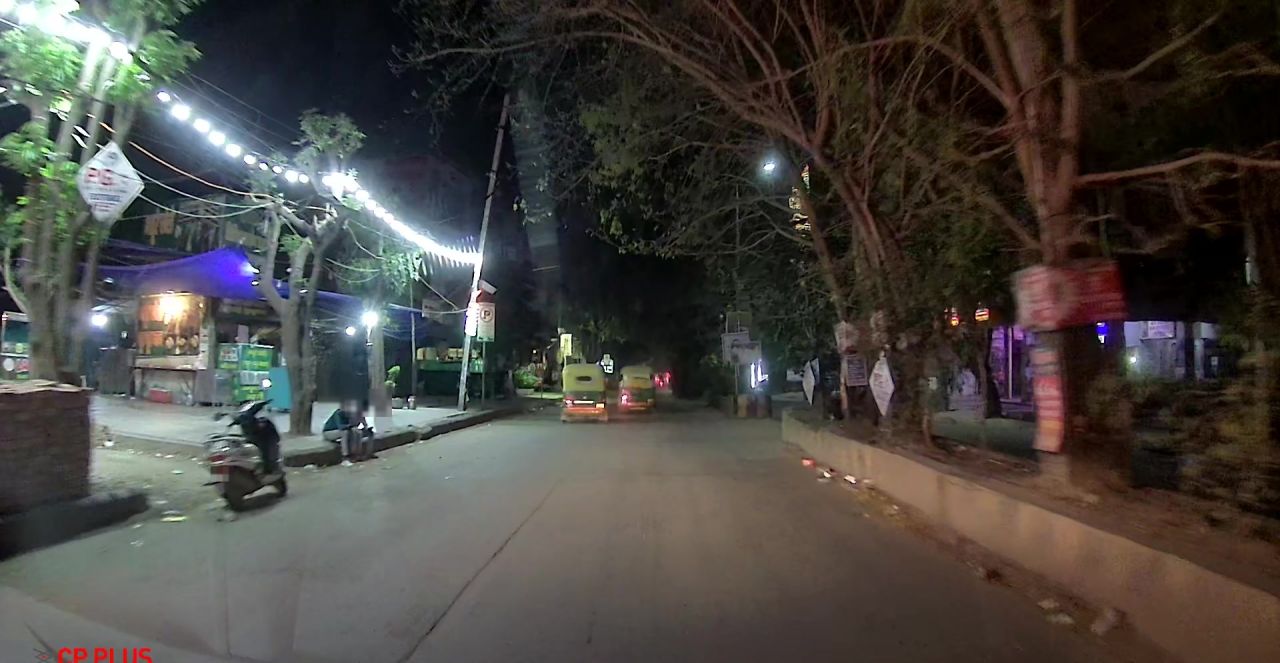
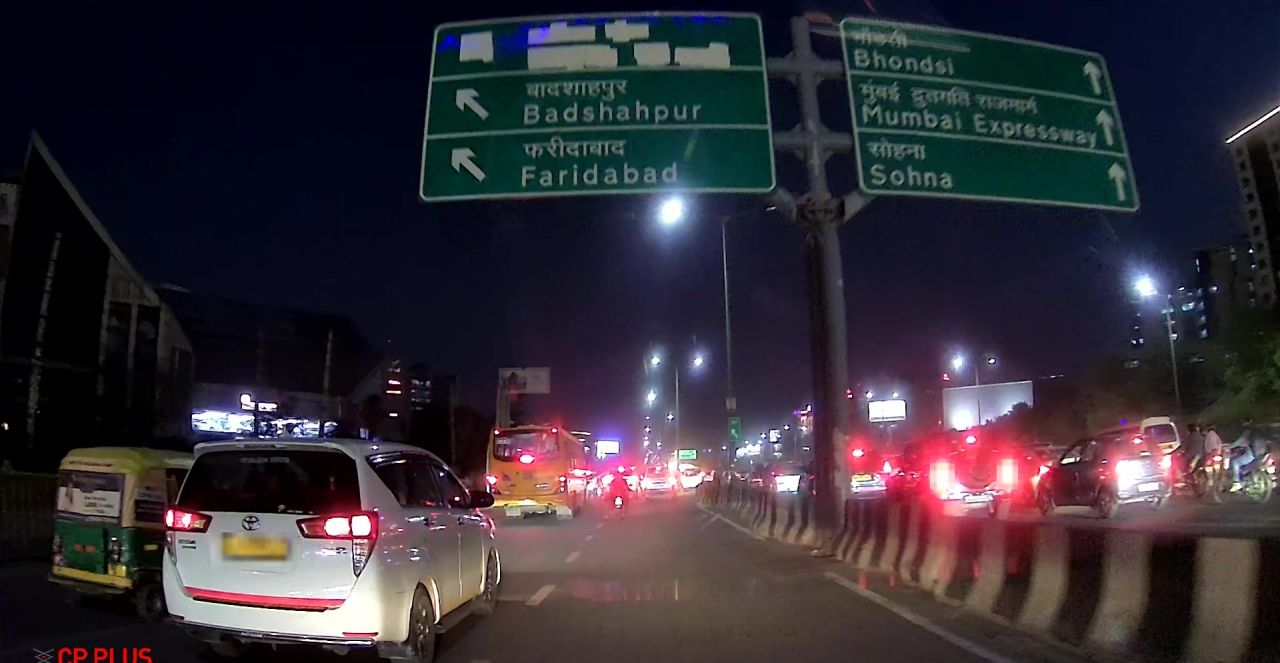
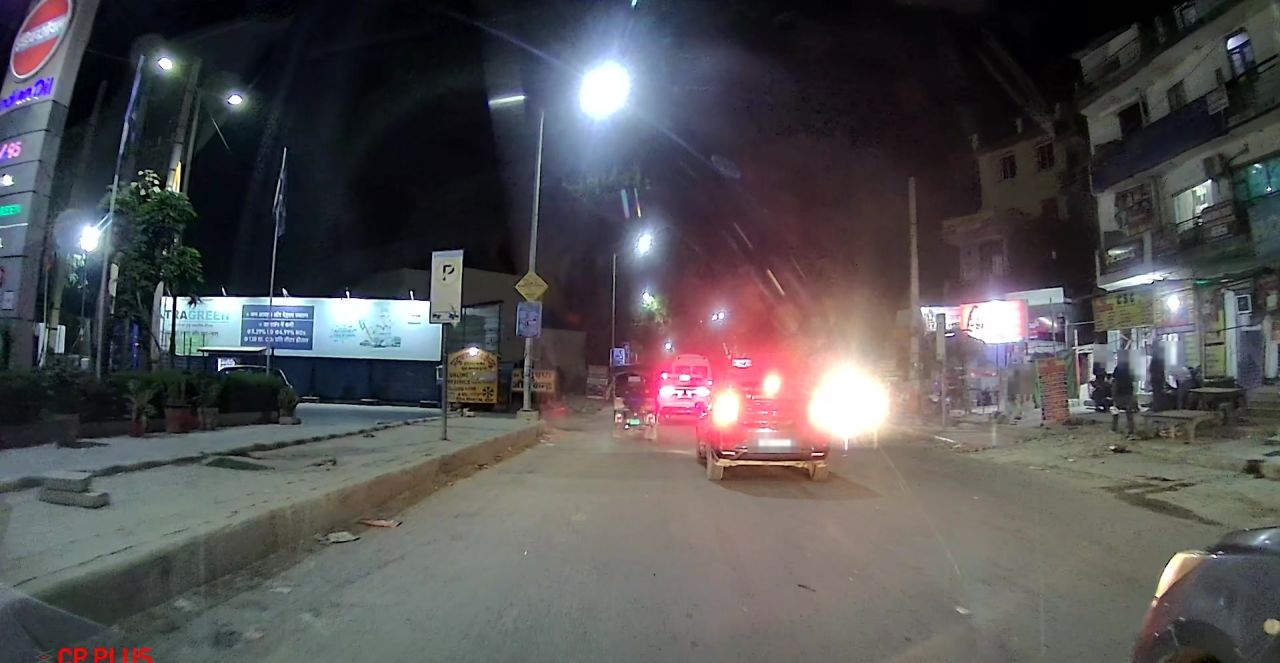
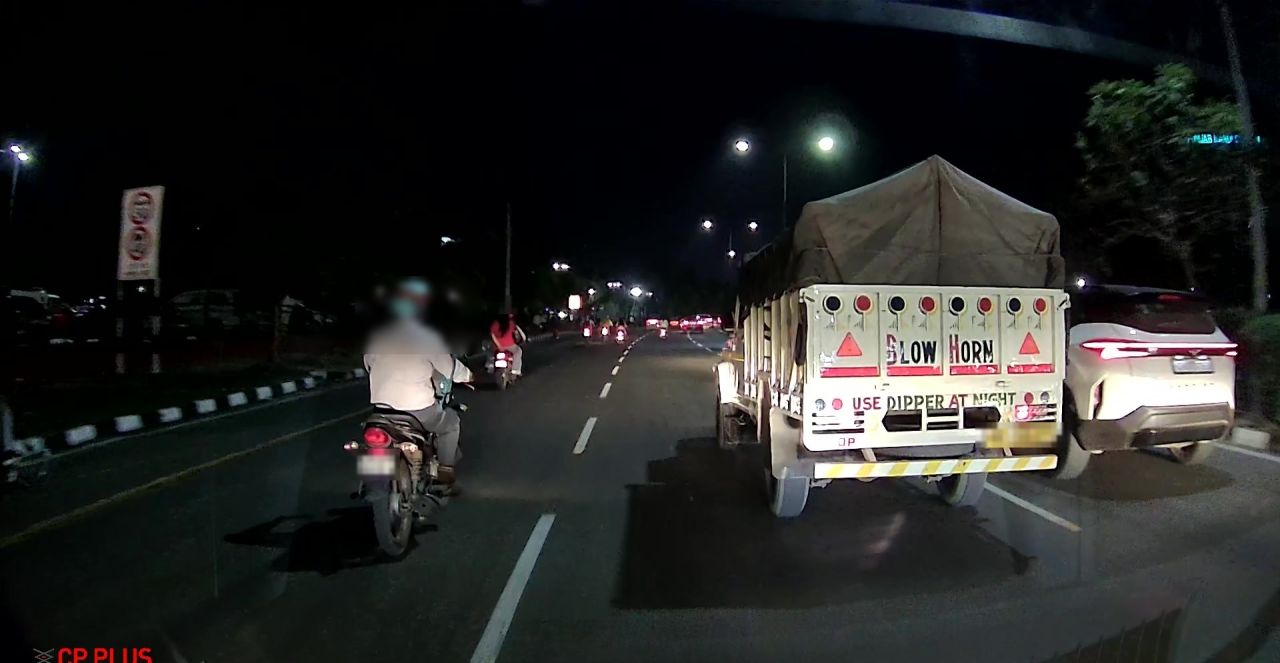
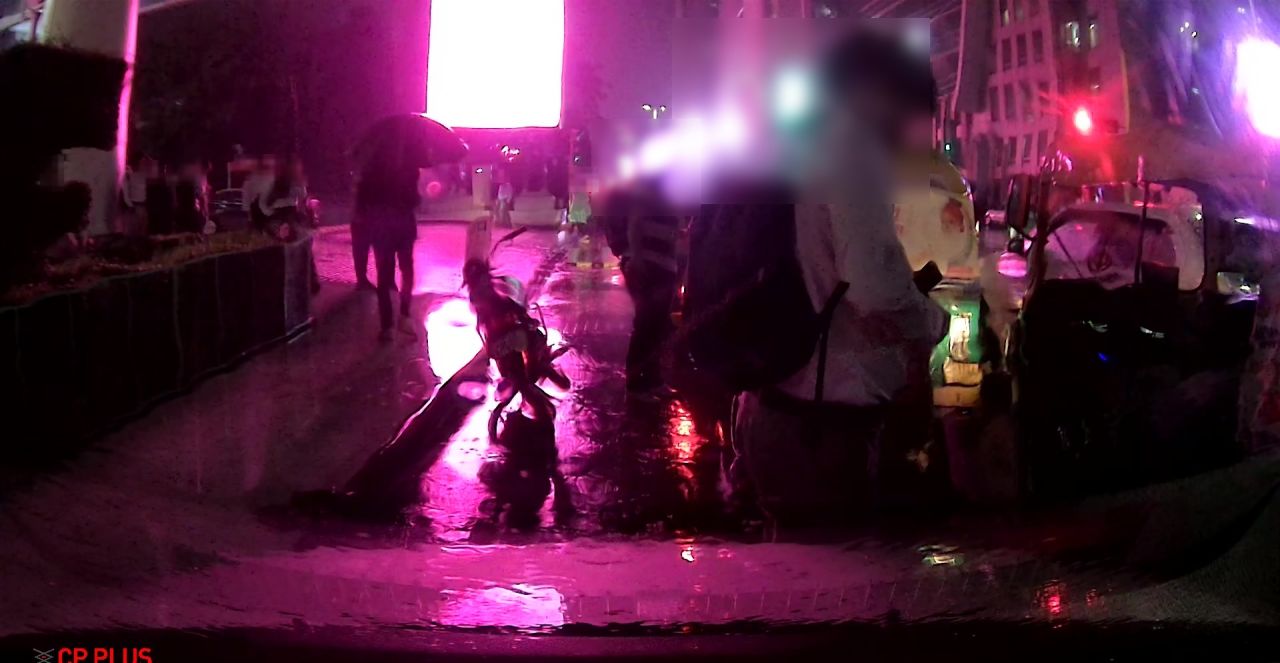
From the test set
12 frames from the 904, across the conditions we score. Faces, number plates and numbers painted on vehicles are blurred.
How we scored it
Test set. 904 frames from Delhi NCR dashcams: 320 by day, 119 at dusk or dawn and 465 at night, 110 of them in rain. A person checked each frame's time of day and weather by hand, and we left out the few frames with no usable picture. Two annotators labelled each frame without seeing the other's work. A box both of them drew counts as ground truth (5,207 boxes). A box only one of them drew is left out of scoring until someone adjudicates it, so a model is neither rewarded nor punished there.
Classes. Person, bicycle, car, motorcycle, bus, truck, traffic light and animal. A COCO "person" counts for our riders too, since COCO has no rider class. Traffic signs are left out: COCO only knows stop signs.
Models. Each runs with its published COCO weights and its default input size, keeping up to 100 boxes per frame above 1% confidence. Nothing is fine-tuned on our data. Near counts only objects at least 32 pixels tall.
Privacy. We blur faces, number plates and numbers painted on vehicles in every frame we publish.
Preview. The adjudicated test set, where someone settles every box only one annotator drew, will follow. Scores may move by a point or two.
Want your model on the board, or a private evaluation on the conditions you ship into?
Talk to us